
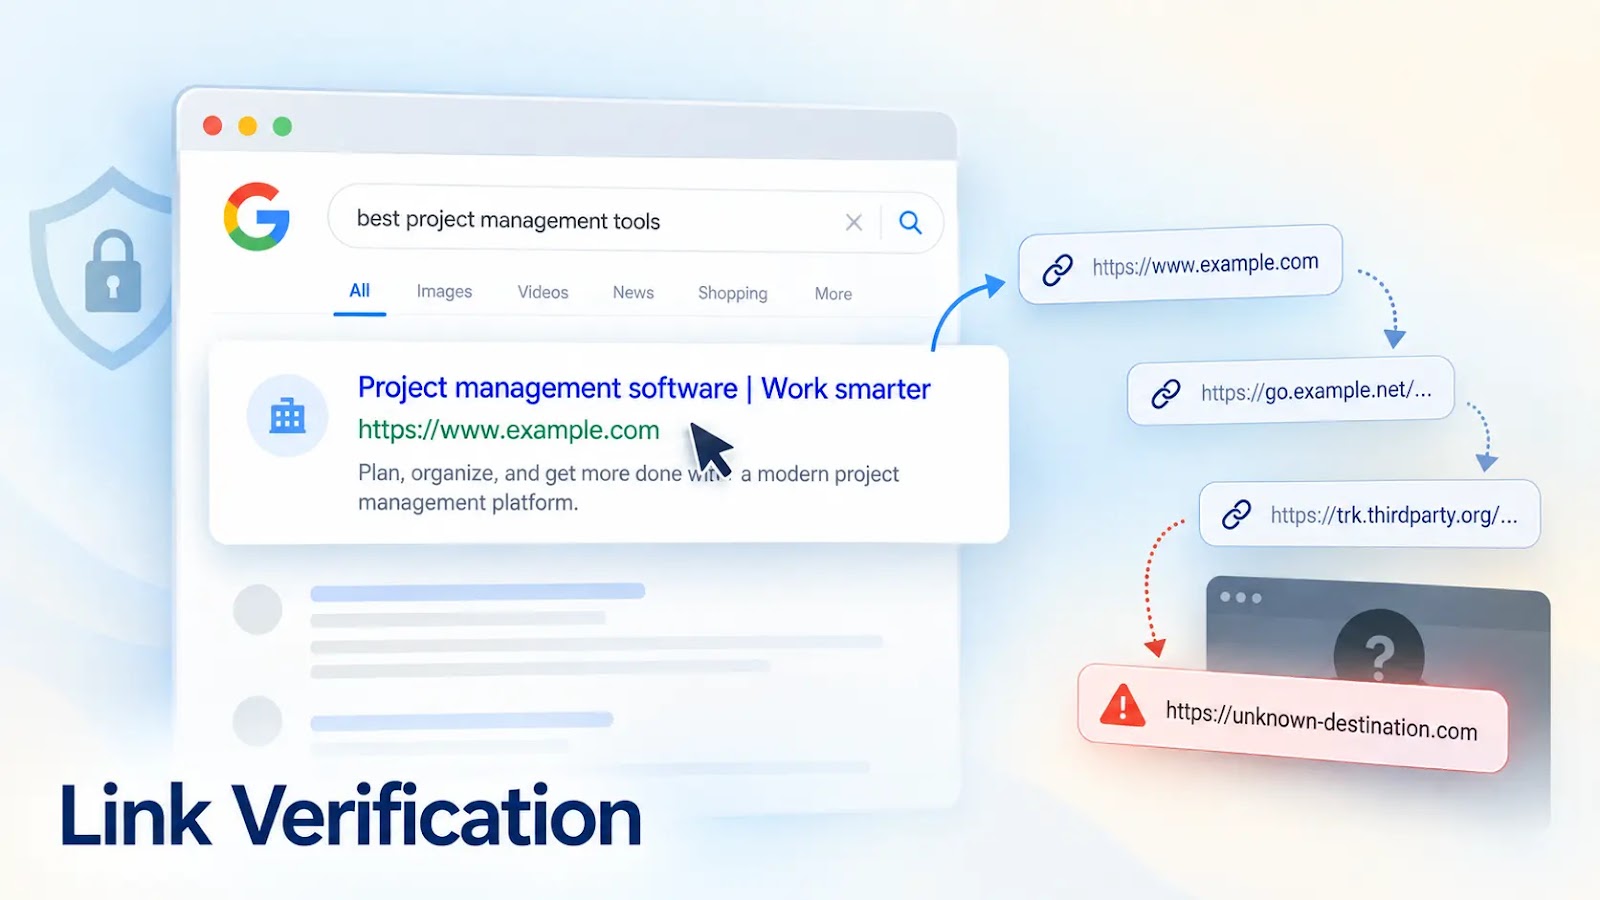
Google Implementing New Link Redirection Practice, Raises Concerns Over User Security
In a significant shift, Google has initiated routing certain organic search result links through a newly implemented redirection system, utilizing opaque links formatted as google.com/goto?url=.... This change diminishes users’ capacity to independently verify the destination URL prior to clicking, raising eyebrows in the digital security realm and among privacy advocates alike.
The primary goal of this new implementation appears to be the elevation of technical and financial barriers to mass scraping, a practice that has increasingly drawn attention from tech companies. While the intent may be to safeguard the platform from automated content extraction, the changes inadvertently undermine a fundamental user habit that goes back years: hovering over links to ascertain their destination. By altering the way links are represented in search results, Google seems to be prioritizing its defensive measures over user transparency.
Under the revised methodology, search result pages on Google no longer embed the original publisher’s URLs directly. Instead, they now serve a Google-controlled passthrough URL featuring an obscure, Google-specific encoded value. This means that when users click on a search result, their browser first contacts Google’s /goto endpoint before they are redirected to the intended final destination. Although the label of the visible site presented above or near the search result remains unchanged, users may find that the hover preview or status bar displays only the intermediary Google URL.
Interestingly, Google has yet to disclose the precise type of abuse that prompted these changes. However, it is reasonable to presume that anti-scraping measures are at the forefront of its motivations. Until now, various entities including rank trackers, SEO platforms, research institutions, archival services, and alternative search engines could conveniently extract destination URLs directly from Google’s search result page HTML. With the new redirection framework in place, automated data collectors face the new challenge of resolving each google.com/goto link individually to discover where it ultimately leads.
In terms of technical feasibility, search-data provider Autom has indicated that the final destination URL is still accessible in the HTTP redirect response’s Location header. This implies that data collectors must send a request to the /goto URL without automatically following the redirect, thereby having to examine the returned Location value. This added step significantly complicates the collection process, resulting in at least one additional lookup for each search result. Consequently, Google gains an enhanced ability to impose request limits, apply behavioral analysis, detect bots, and enforce access controls on automated requests.
The implementation of this new system introduces a notable concern regarding transparency for end users. Long-standing security best practices have counseled individuals to hover over links in various formats—be it emails, chat messages, or web pages—to confirm the reliability of the link destination before clicking. However, with Google’s recent development, this hover preview no longer provides independent confirmation of where a user will land upon clicking a link.
It’s crucial to note that while this redirection scheme doesn’t inherently imply that Google is directing users to malicious sites, the change does obscure the destination URLs. This has significant implications, particularly for users attempting to differentiate between legitimate brands and potential threats posed by lookalike brands, typosquatted domains, and sponsored content impersonation. The visible domain label may still be available, but it no longer serves as a reliable check against the actual clickable URL.
For users who prioritize security, the ability to compare the displayed domain with hyperlink targets, SSL certificate details, and contextual signals is vital. The new design adversely affects this first layer of protection, making it substantially less effective when users need it most—just prior to navigating away from search results.
The ramifications of this shift extend beyond individual users and impacts a range of operations including SEO monitoring, digital forensics, accessibility tooling, academic research, and web archiving. Independent indexing services may now confront extra infrastructural costs and exposure to rate-limiting based on the necessity for server-side resolution for each search result.
This facet has not gone unnoticed in community discussions, where participants highlight a notable irony. Google’s own search engine relies heavily on automated collection of publicly accessible web content, yet it has made its own search results increasingly difficult to gather programmatically.
In light of these developments, security teams and organizations are reminded not to rely solely on hover text for link verification. Organizations are strongly encouraged to reinforce multi-faceted URL-verification protocols, incorporating domain reputation controls, DNS and web filters, browser isolation when necessary, enhanced email security measures, and user education focused on validating domains rather than simply trusting search rankings or visual appearances.
While Google’s new redirection architecture is ostensibly designed to deter large-scale scraping, it simultaneously introduces a Google-controlled opaque layer between users and the links they are expected to trust. This layer raises essential questions about transparency, security, and the implications of technology on the everyday user experience.